All articles
InSitu is an AI on-call agent that places read-only probes on running production code to capture exact variable state at the moment of failure, without a redeploy or restart.
How to let engineers debug production when SSH access is not allowed
No SSH to production? A four-rung ladder for engineers: scoped telemetry, brokered JIT sessions, Kubernetes ephemeral containers, and read-only live variable capture.
Integration and API failures
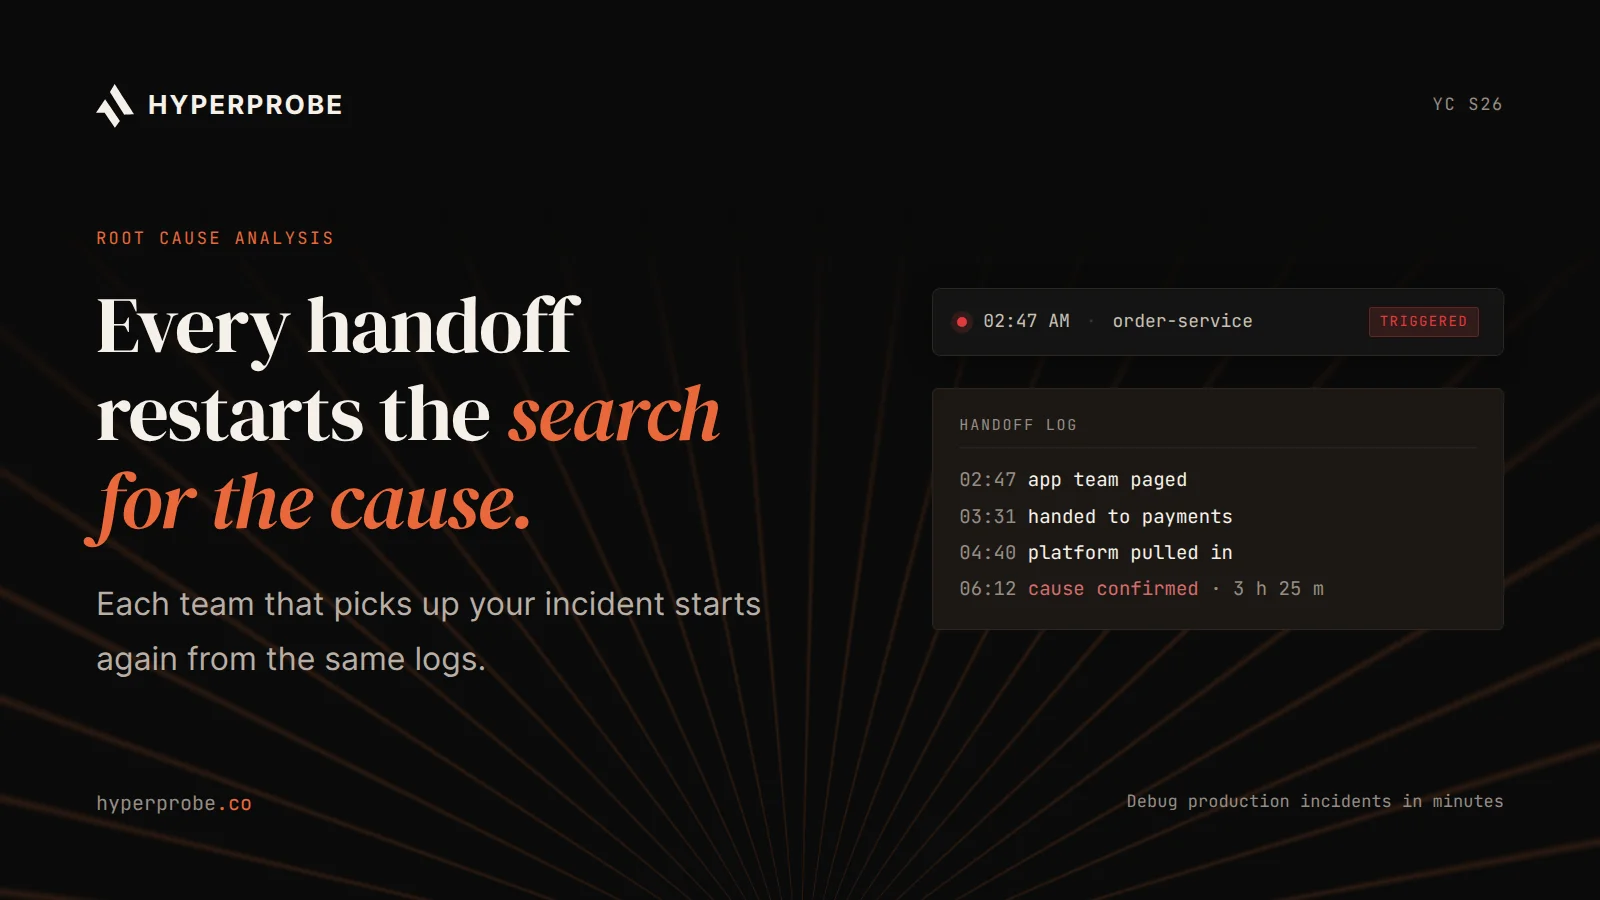
Why root cause analysis takes so long across teams
Root cause analysis in software stalls at team boundaries: green dashboards, unowned seams, mismatched evidence, access gates. See the data and three fixes.
Coding agents in production
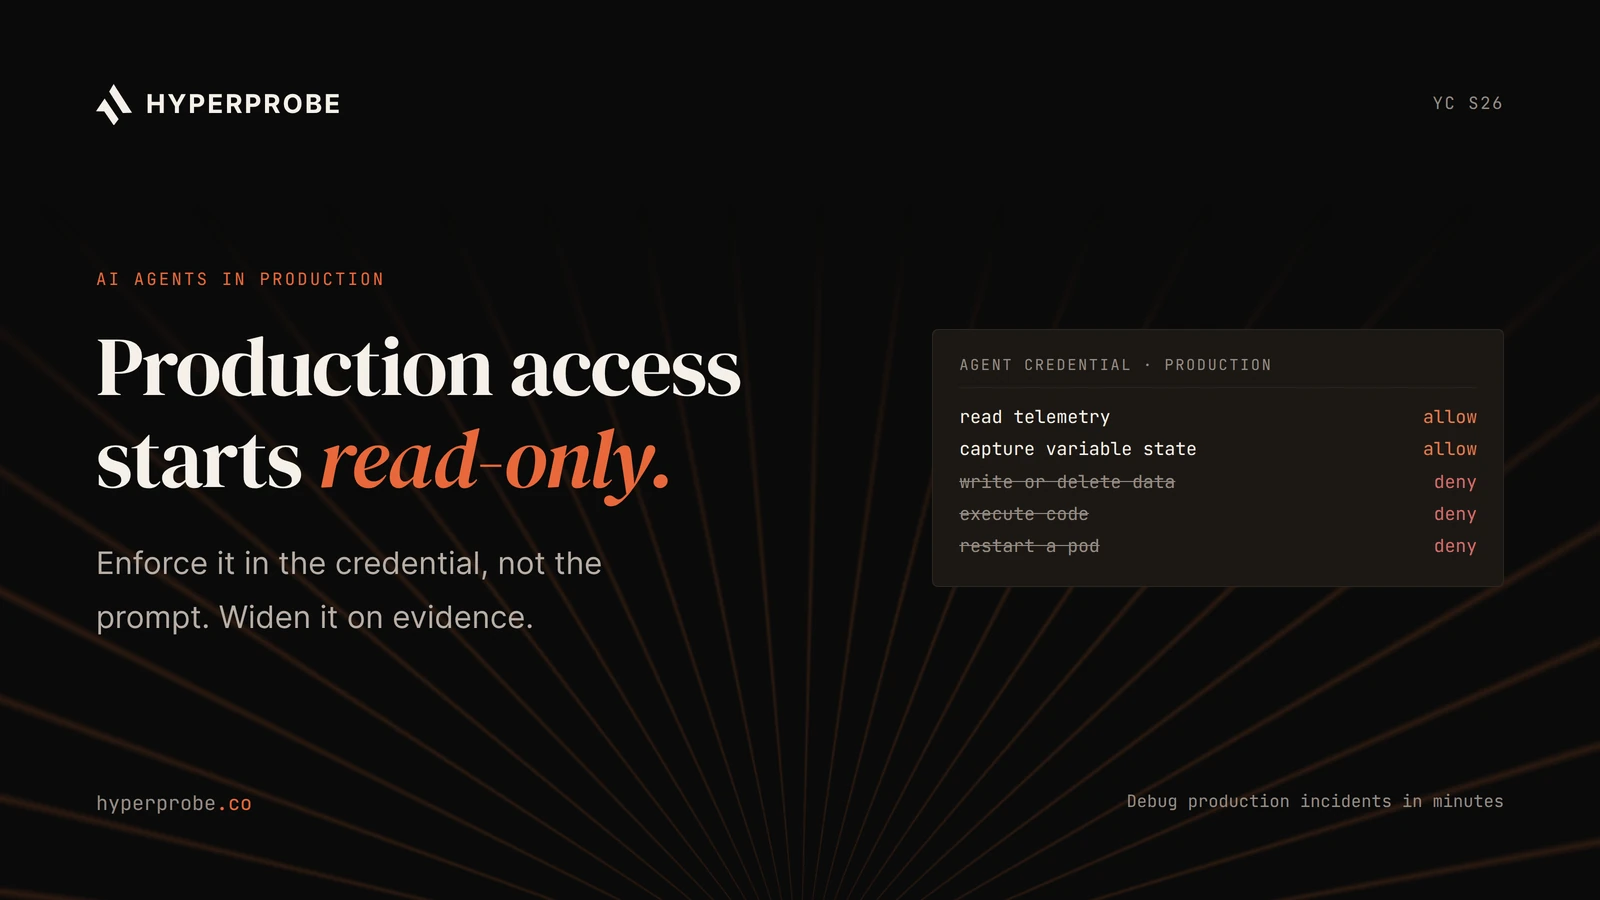
Should you let AI agents access production? The read-only boundary to require first
Should we let AI agents access production systems? Yes, behind a read-only boundary enforced below the model. What that boundary must include, with a staged trust model and checklist.
Coding agents in production
How to debug production when you cannot store customer data
A practical ladder for debugging production under GDPR, PCI or HIPAA limits: aggregates, hashed references, scoped debug flags and redacted line-level captures.
AI SRE and incident tooling
MTTD vs MTTR when the failure never raises an error
MTTD measured from alerts hides silent failures that run for days. Learn how MTTD differs from MTTR, how to measure detection from true onset, and how to shrink both.
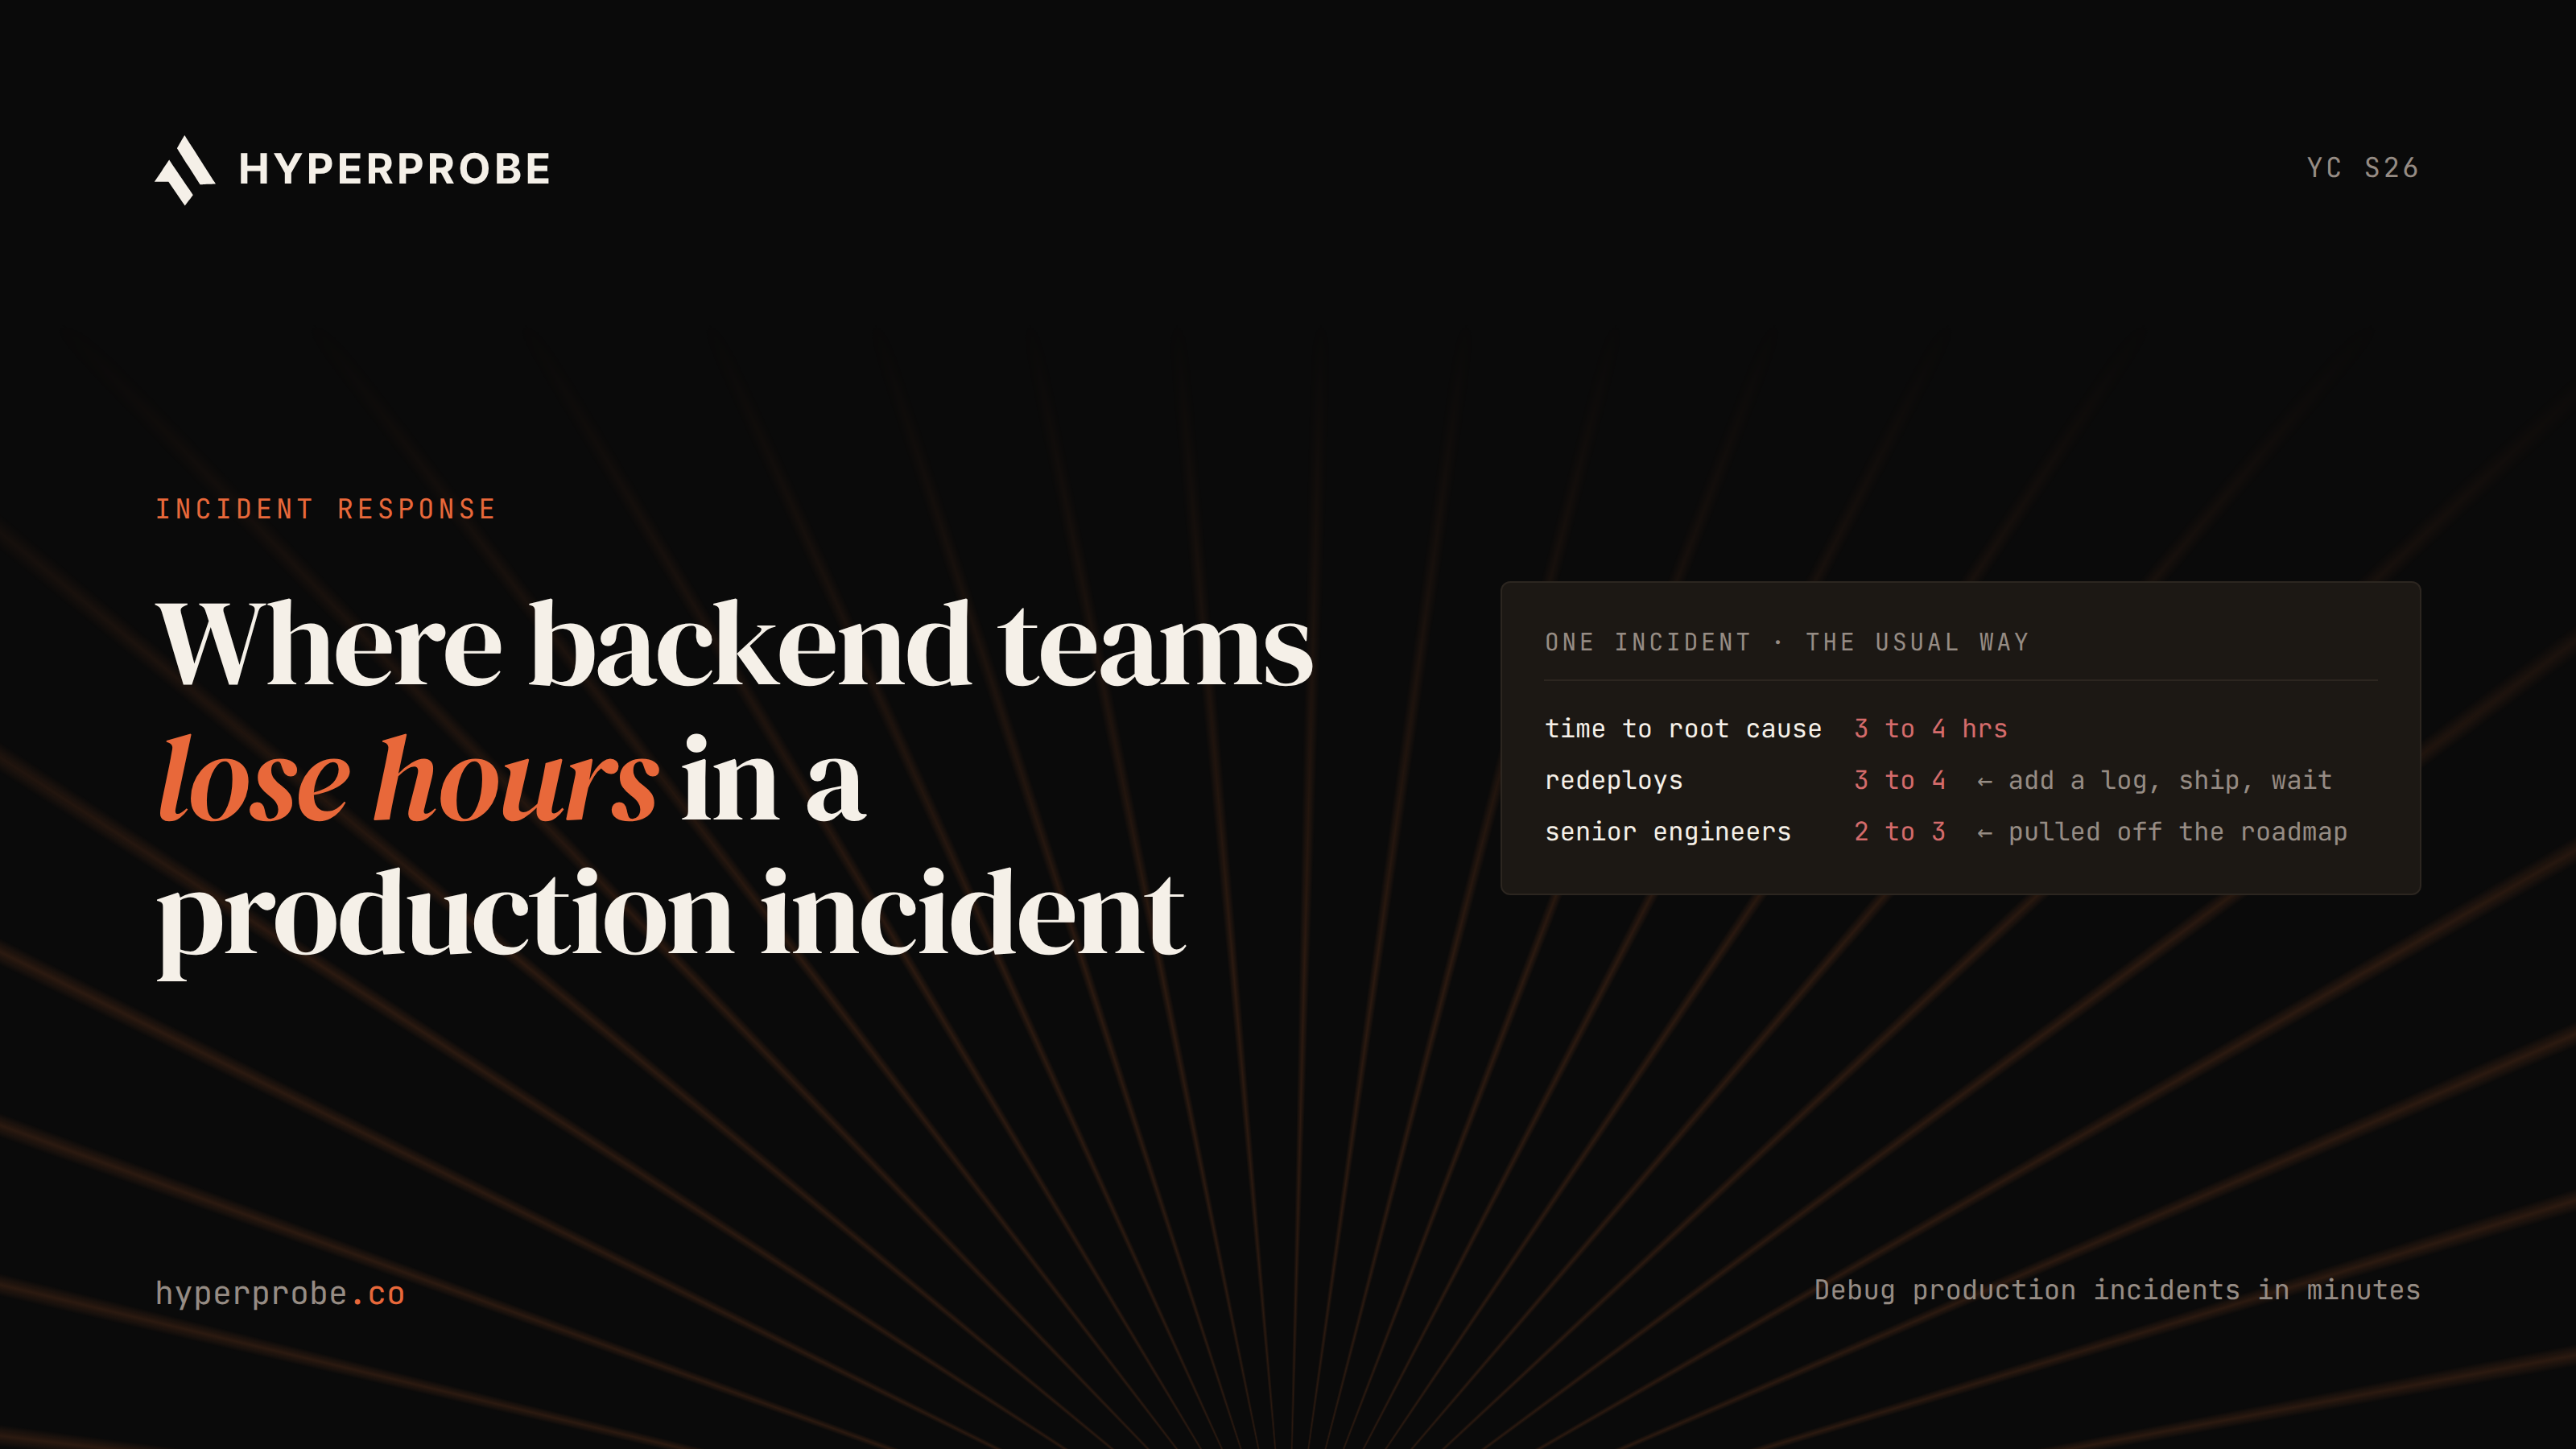
Where backend teams lose hours in a production incident
Mean time to resolution hides a lopsided split: detection is a tenth, investigation over half. See where backend incident hours go and how to audit yours.
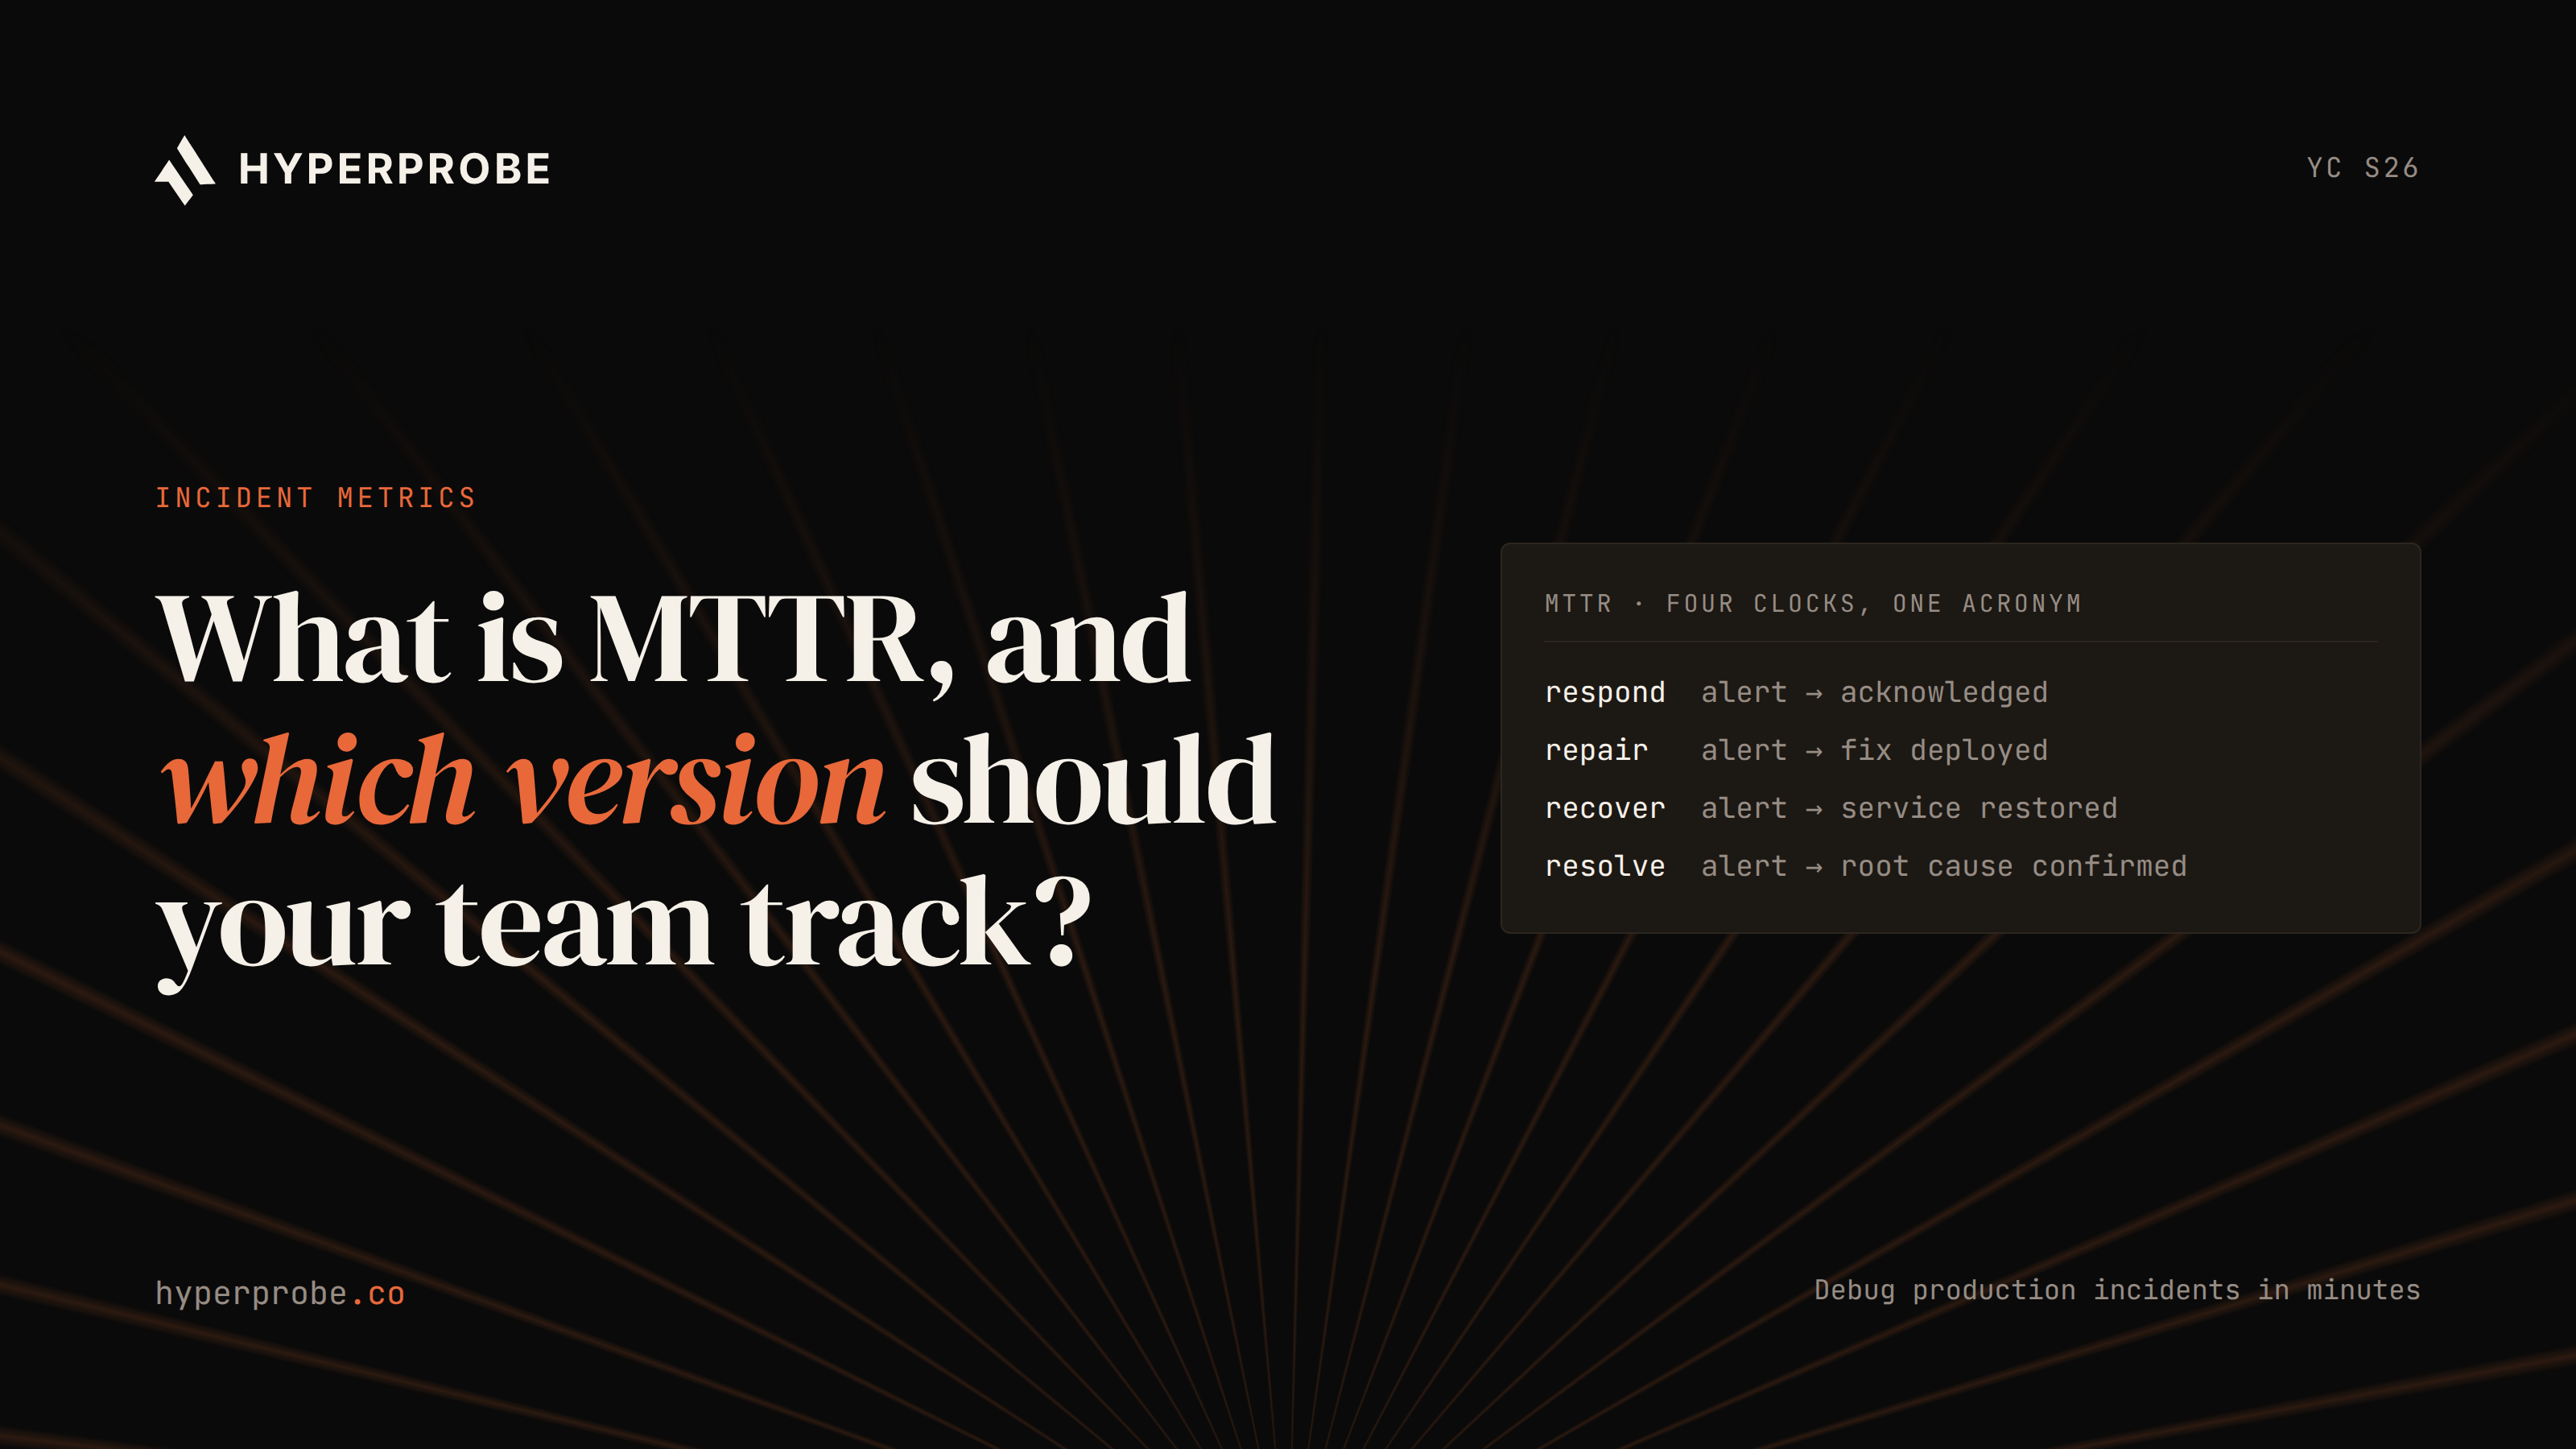
What is MTTR, and which version should your team track?
MTTR can mean repair, recovery, respond, or resolve. Learn what each version measures, how DORA redefined it, why the mean misleads, and which one your team should track.
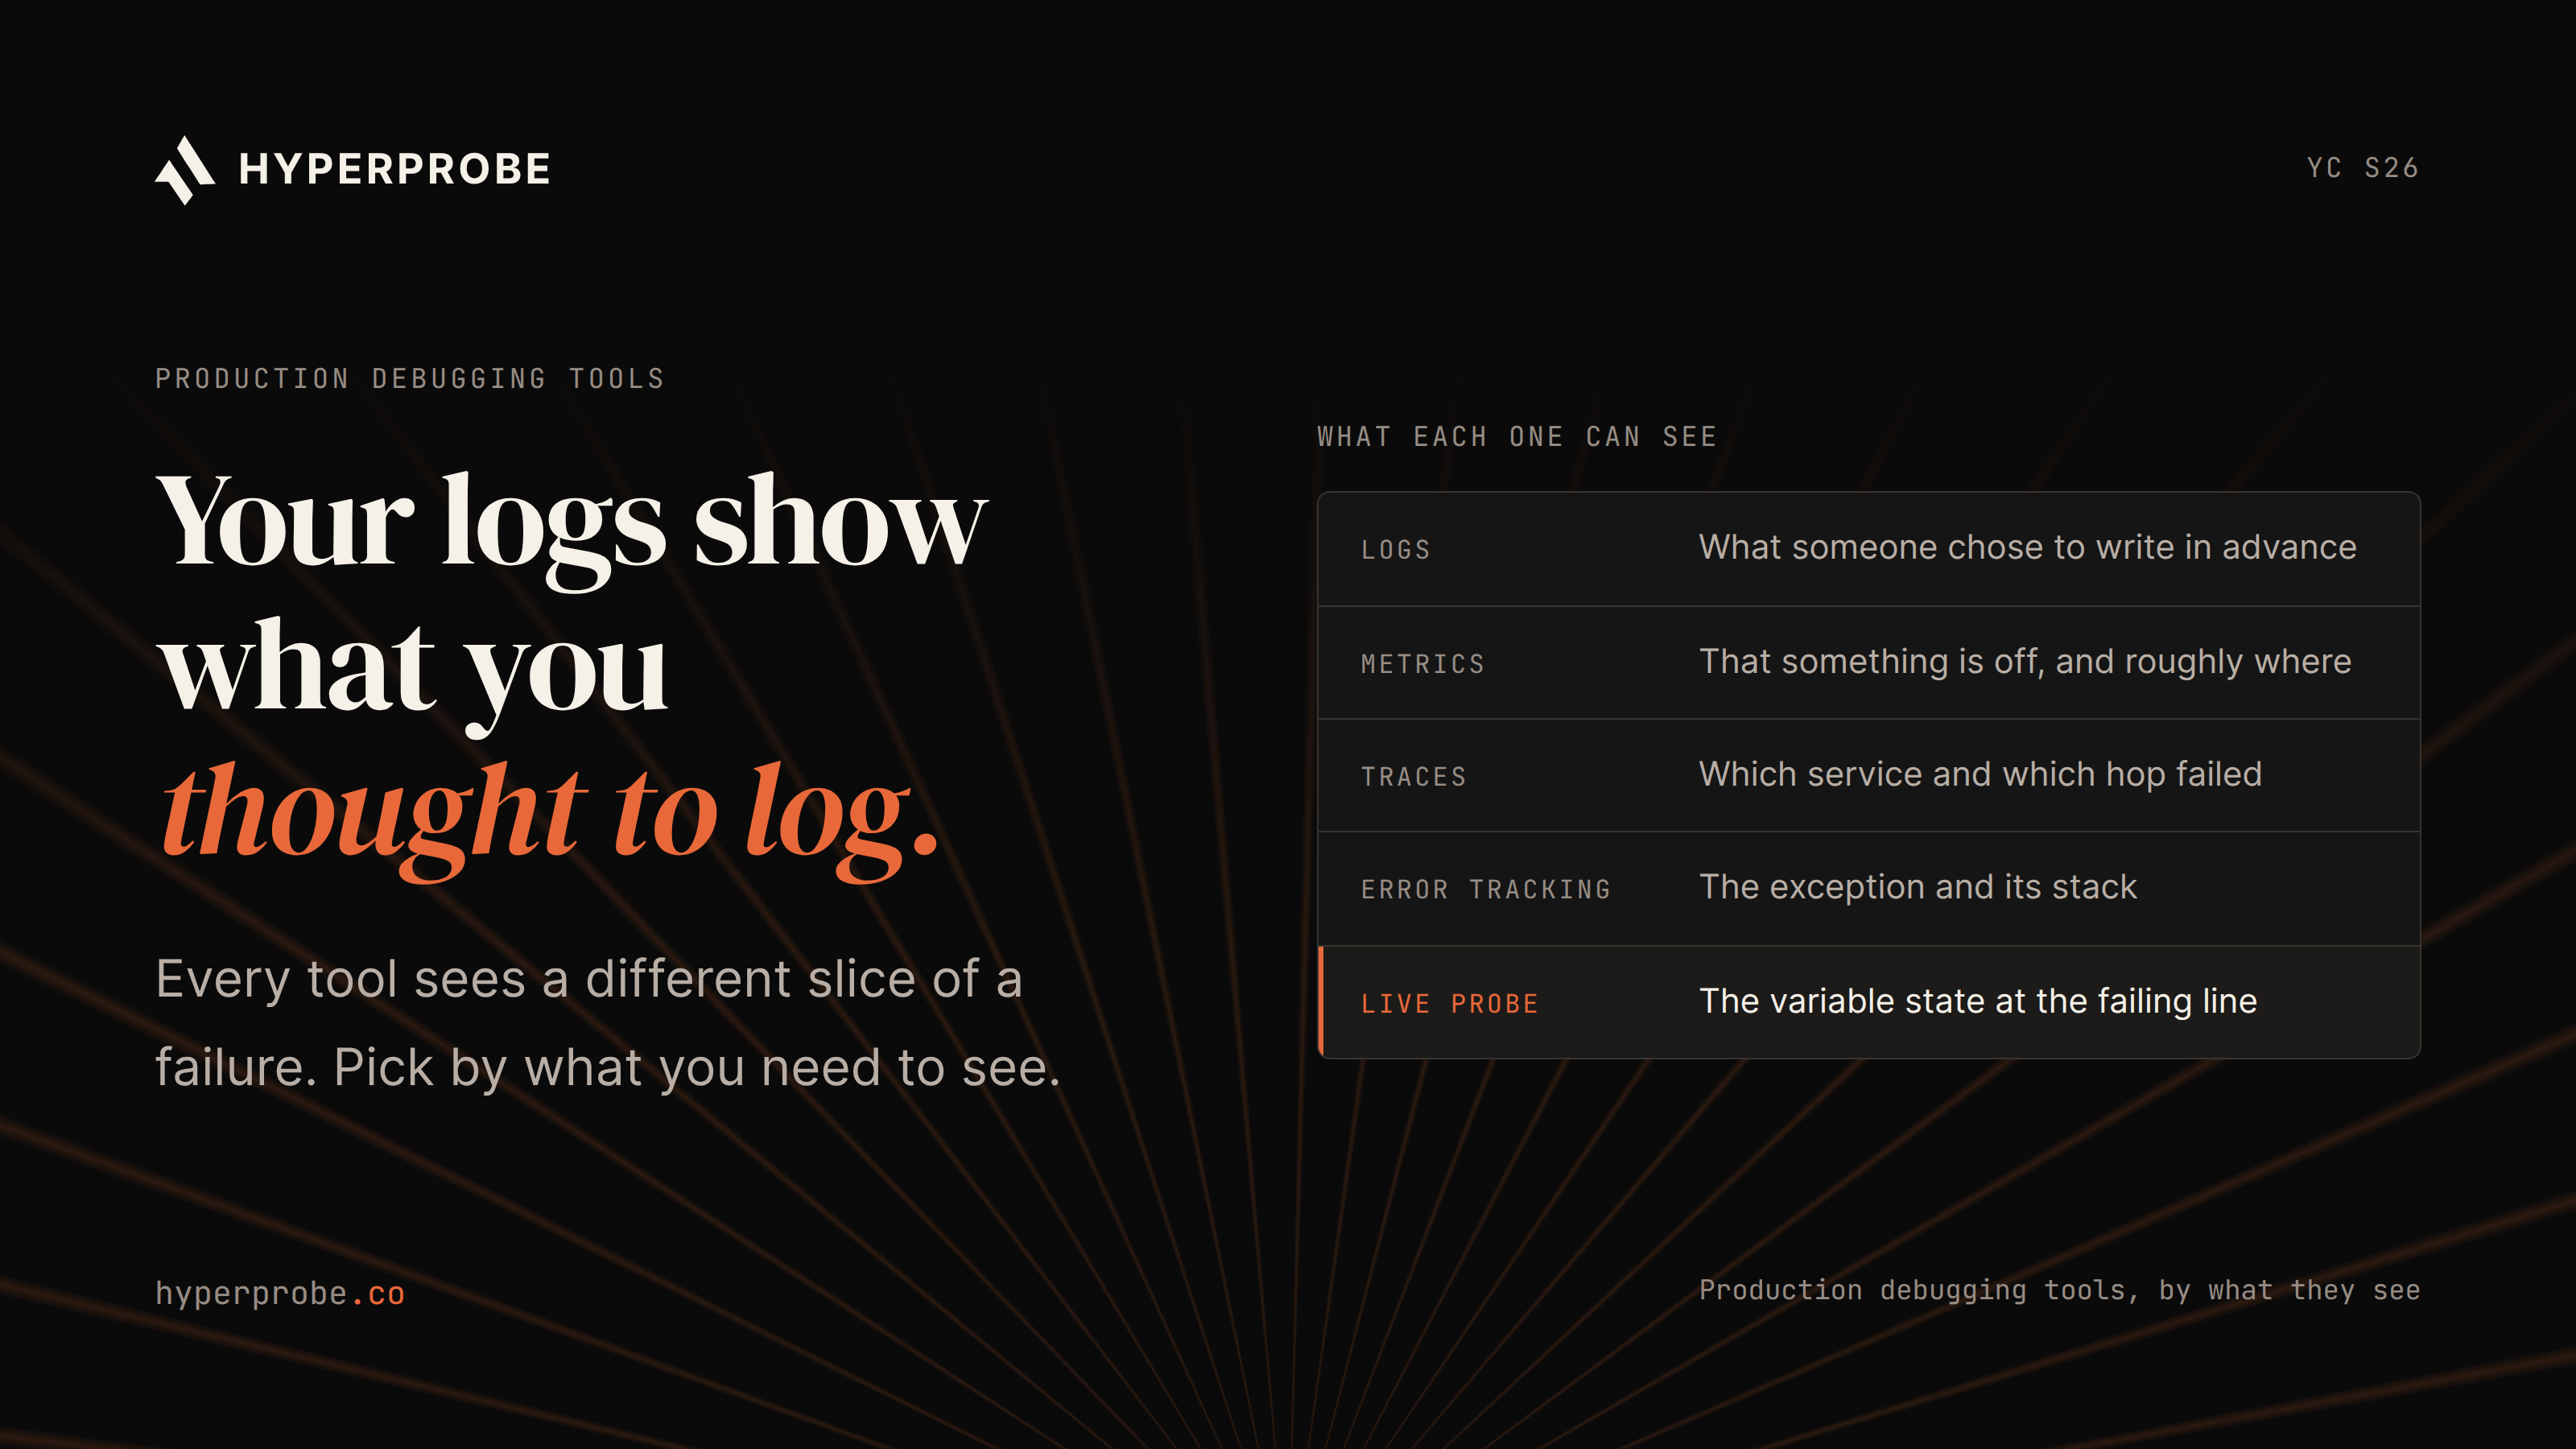
Best debugging tools for production, by what each one can see
Compare logs, APM, tracing, error tracking, profiling, debuggers and dynamic instrumentation by what each sees and misses in a production failure.
Runtime state and performance
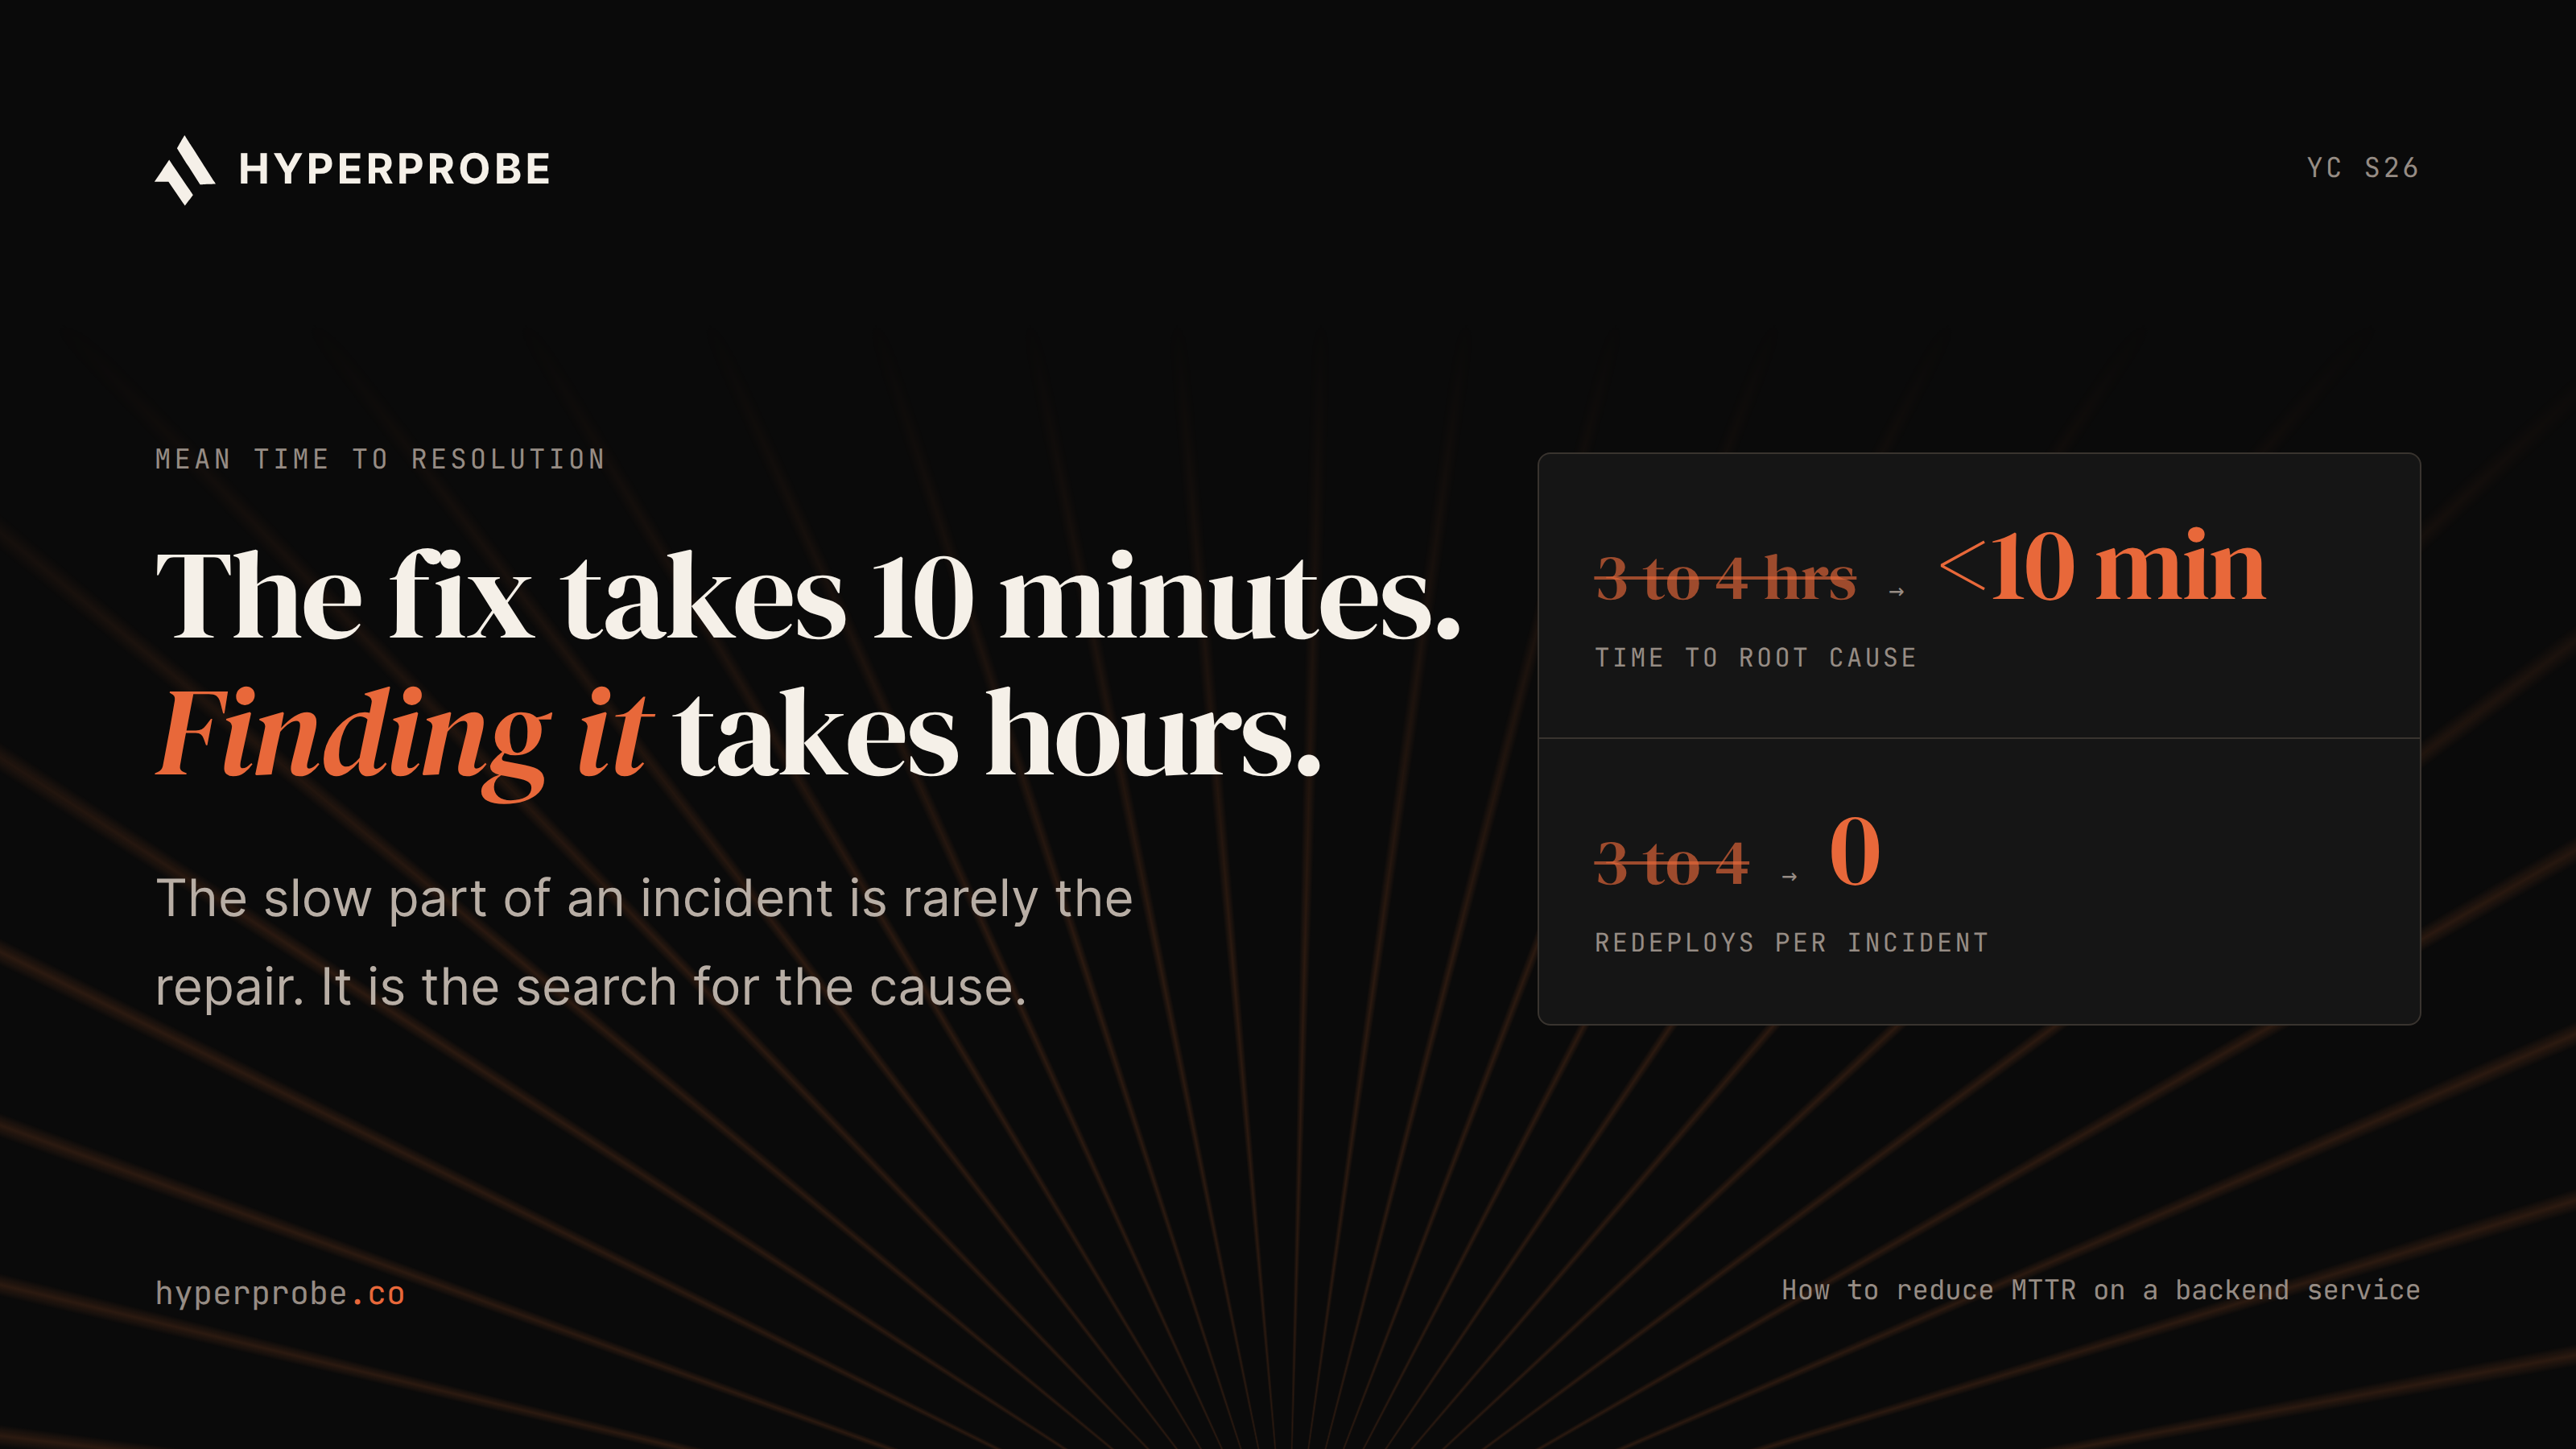
How to Reduce Mean Time to Resolution on a Backend Service?
Learn how to reduce MTTR on a backend service by measuring diagnosis, avoiding information-only redeploys, and confirming root cause with evidence.
Production debugging and RCA
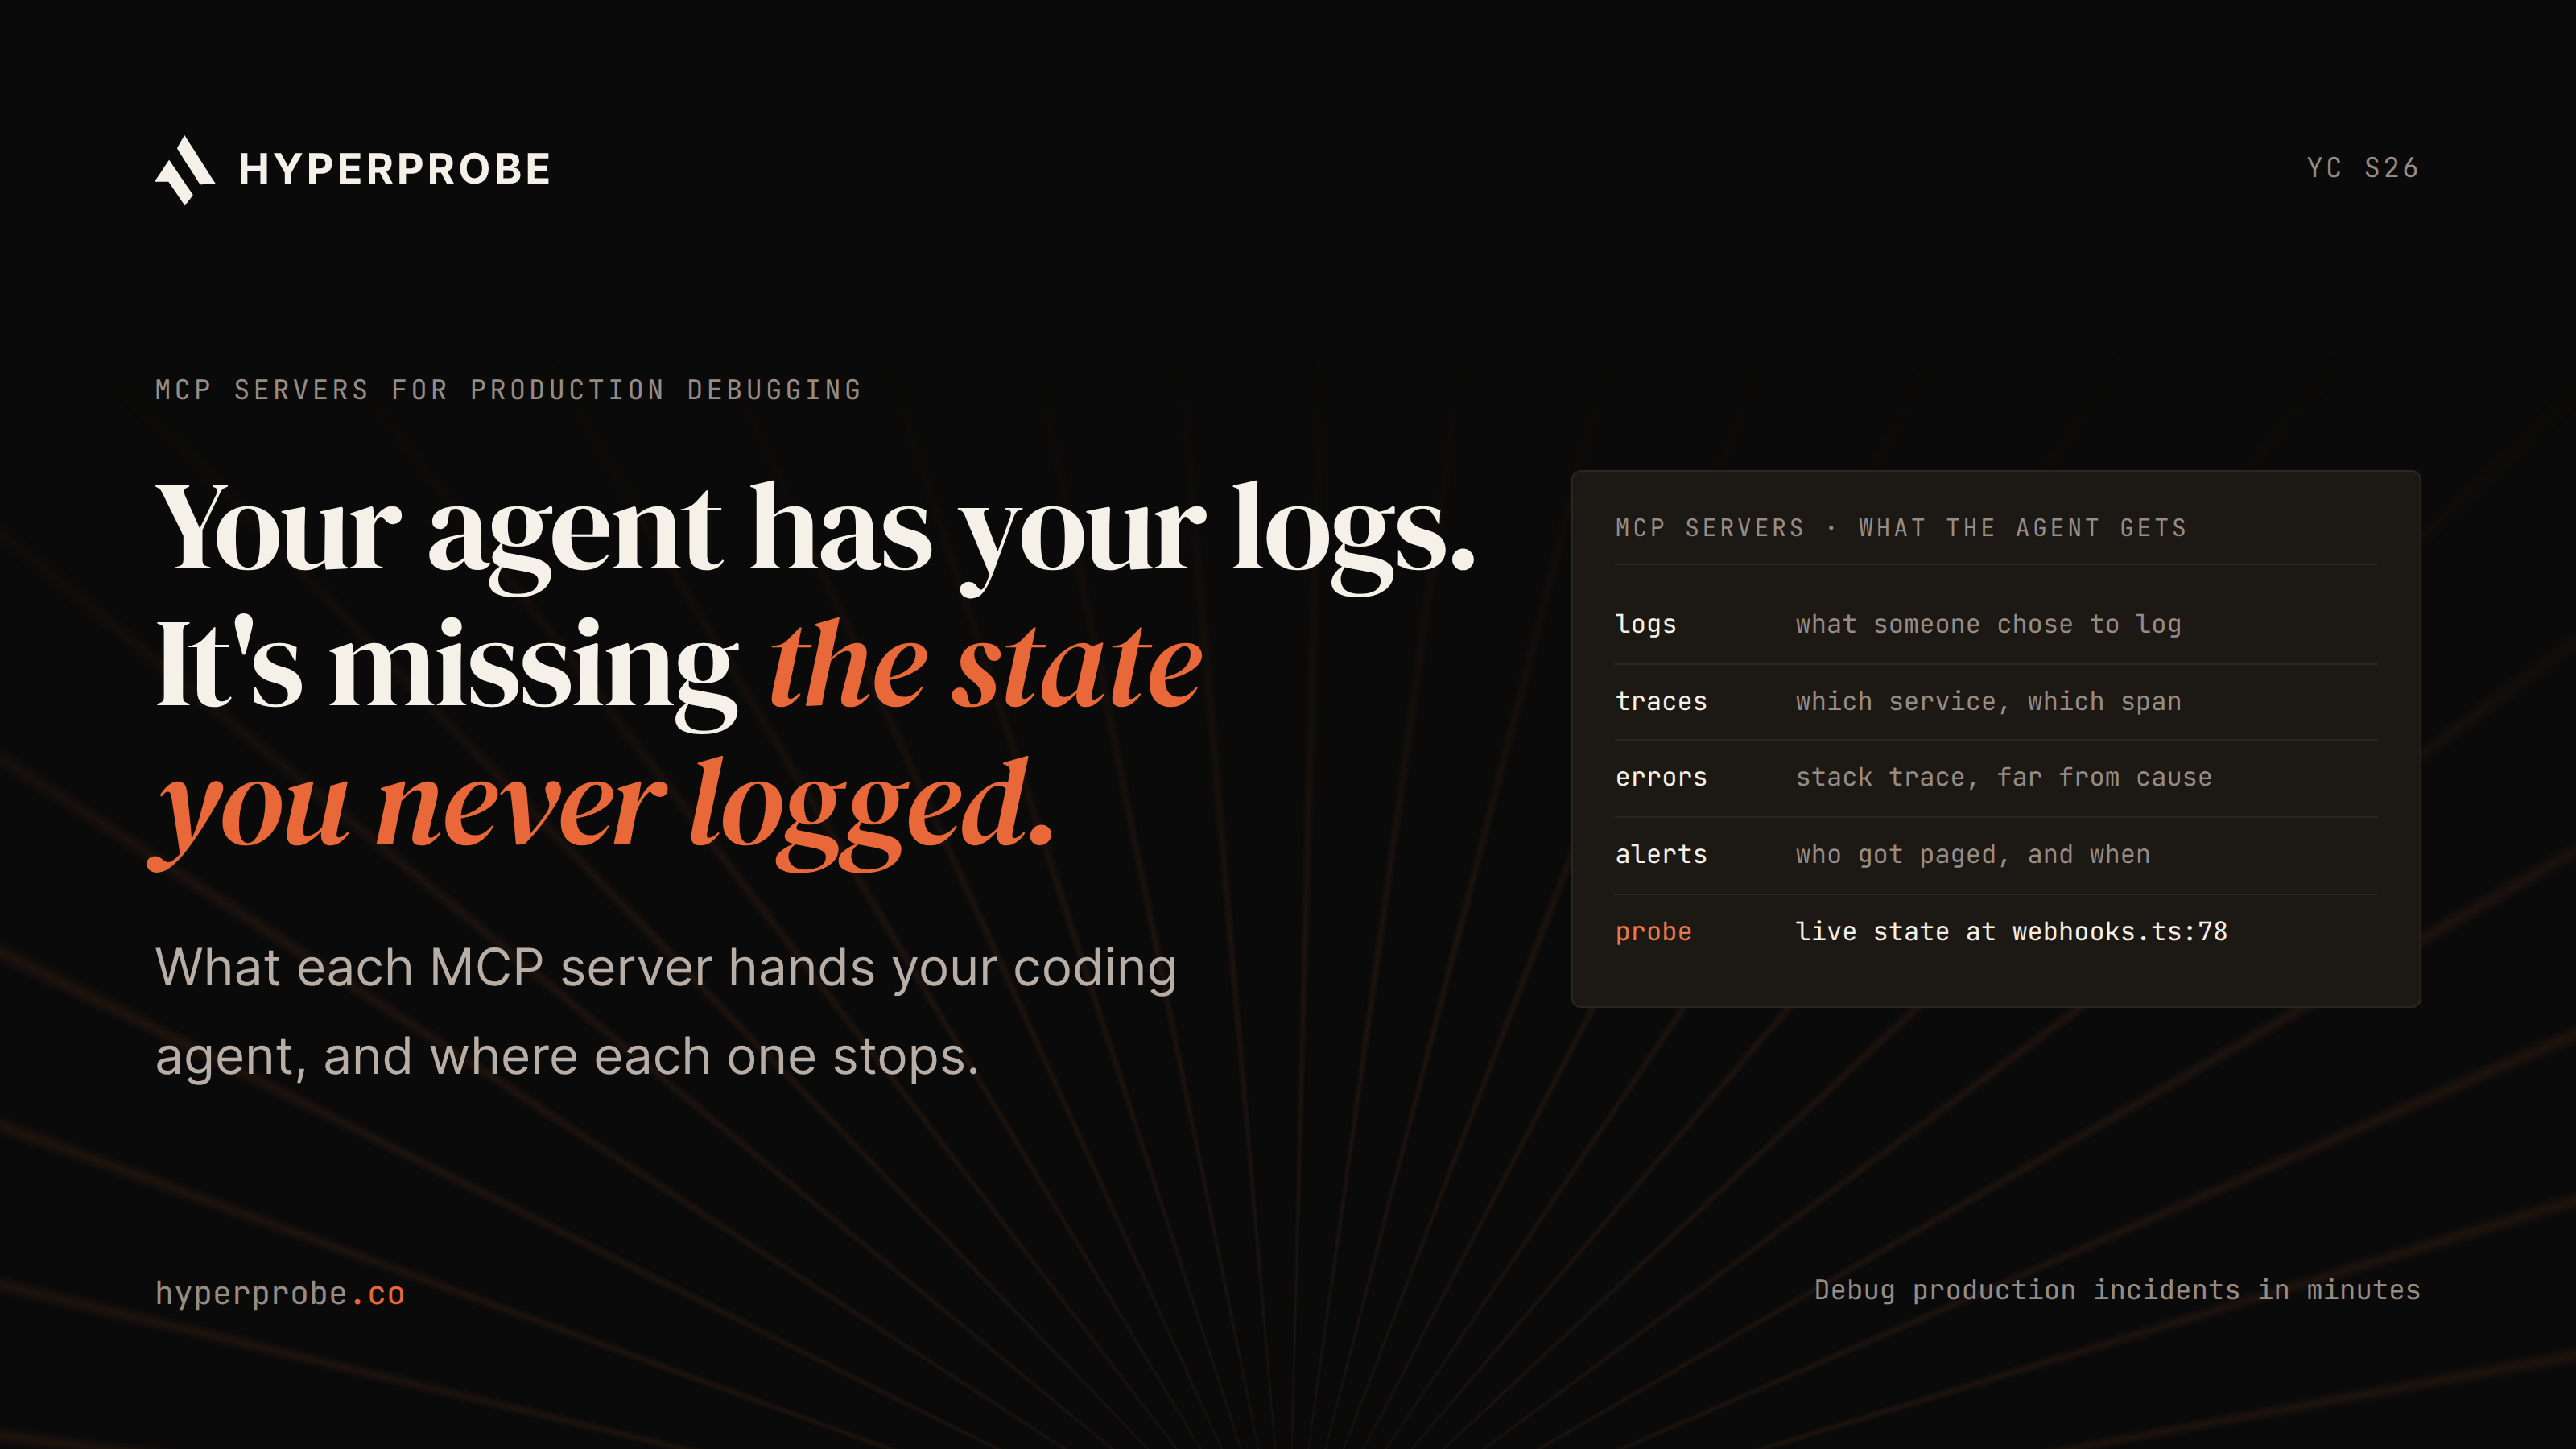
MCP servers for debugging production and what each gives an agent
Compare Claude Code MCP servers for production debugging, including Sentry, Datadog, PagerDuty, Honeycomb, Grafana, and debugger MCPs, plus their evidence gaps.
Production debugging and RCA
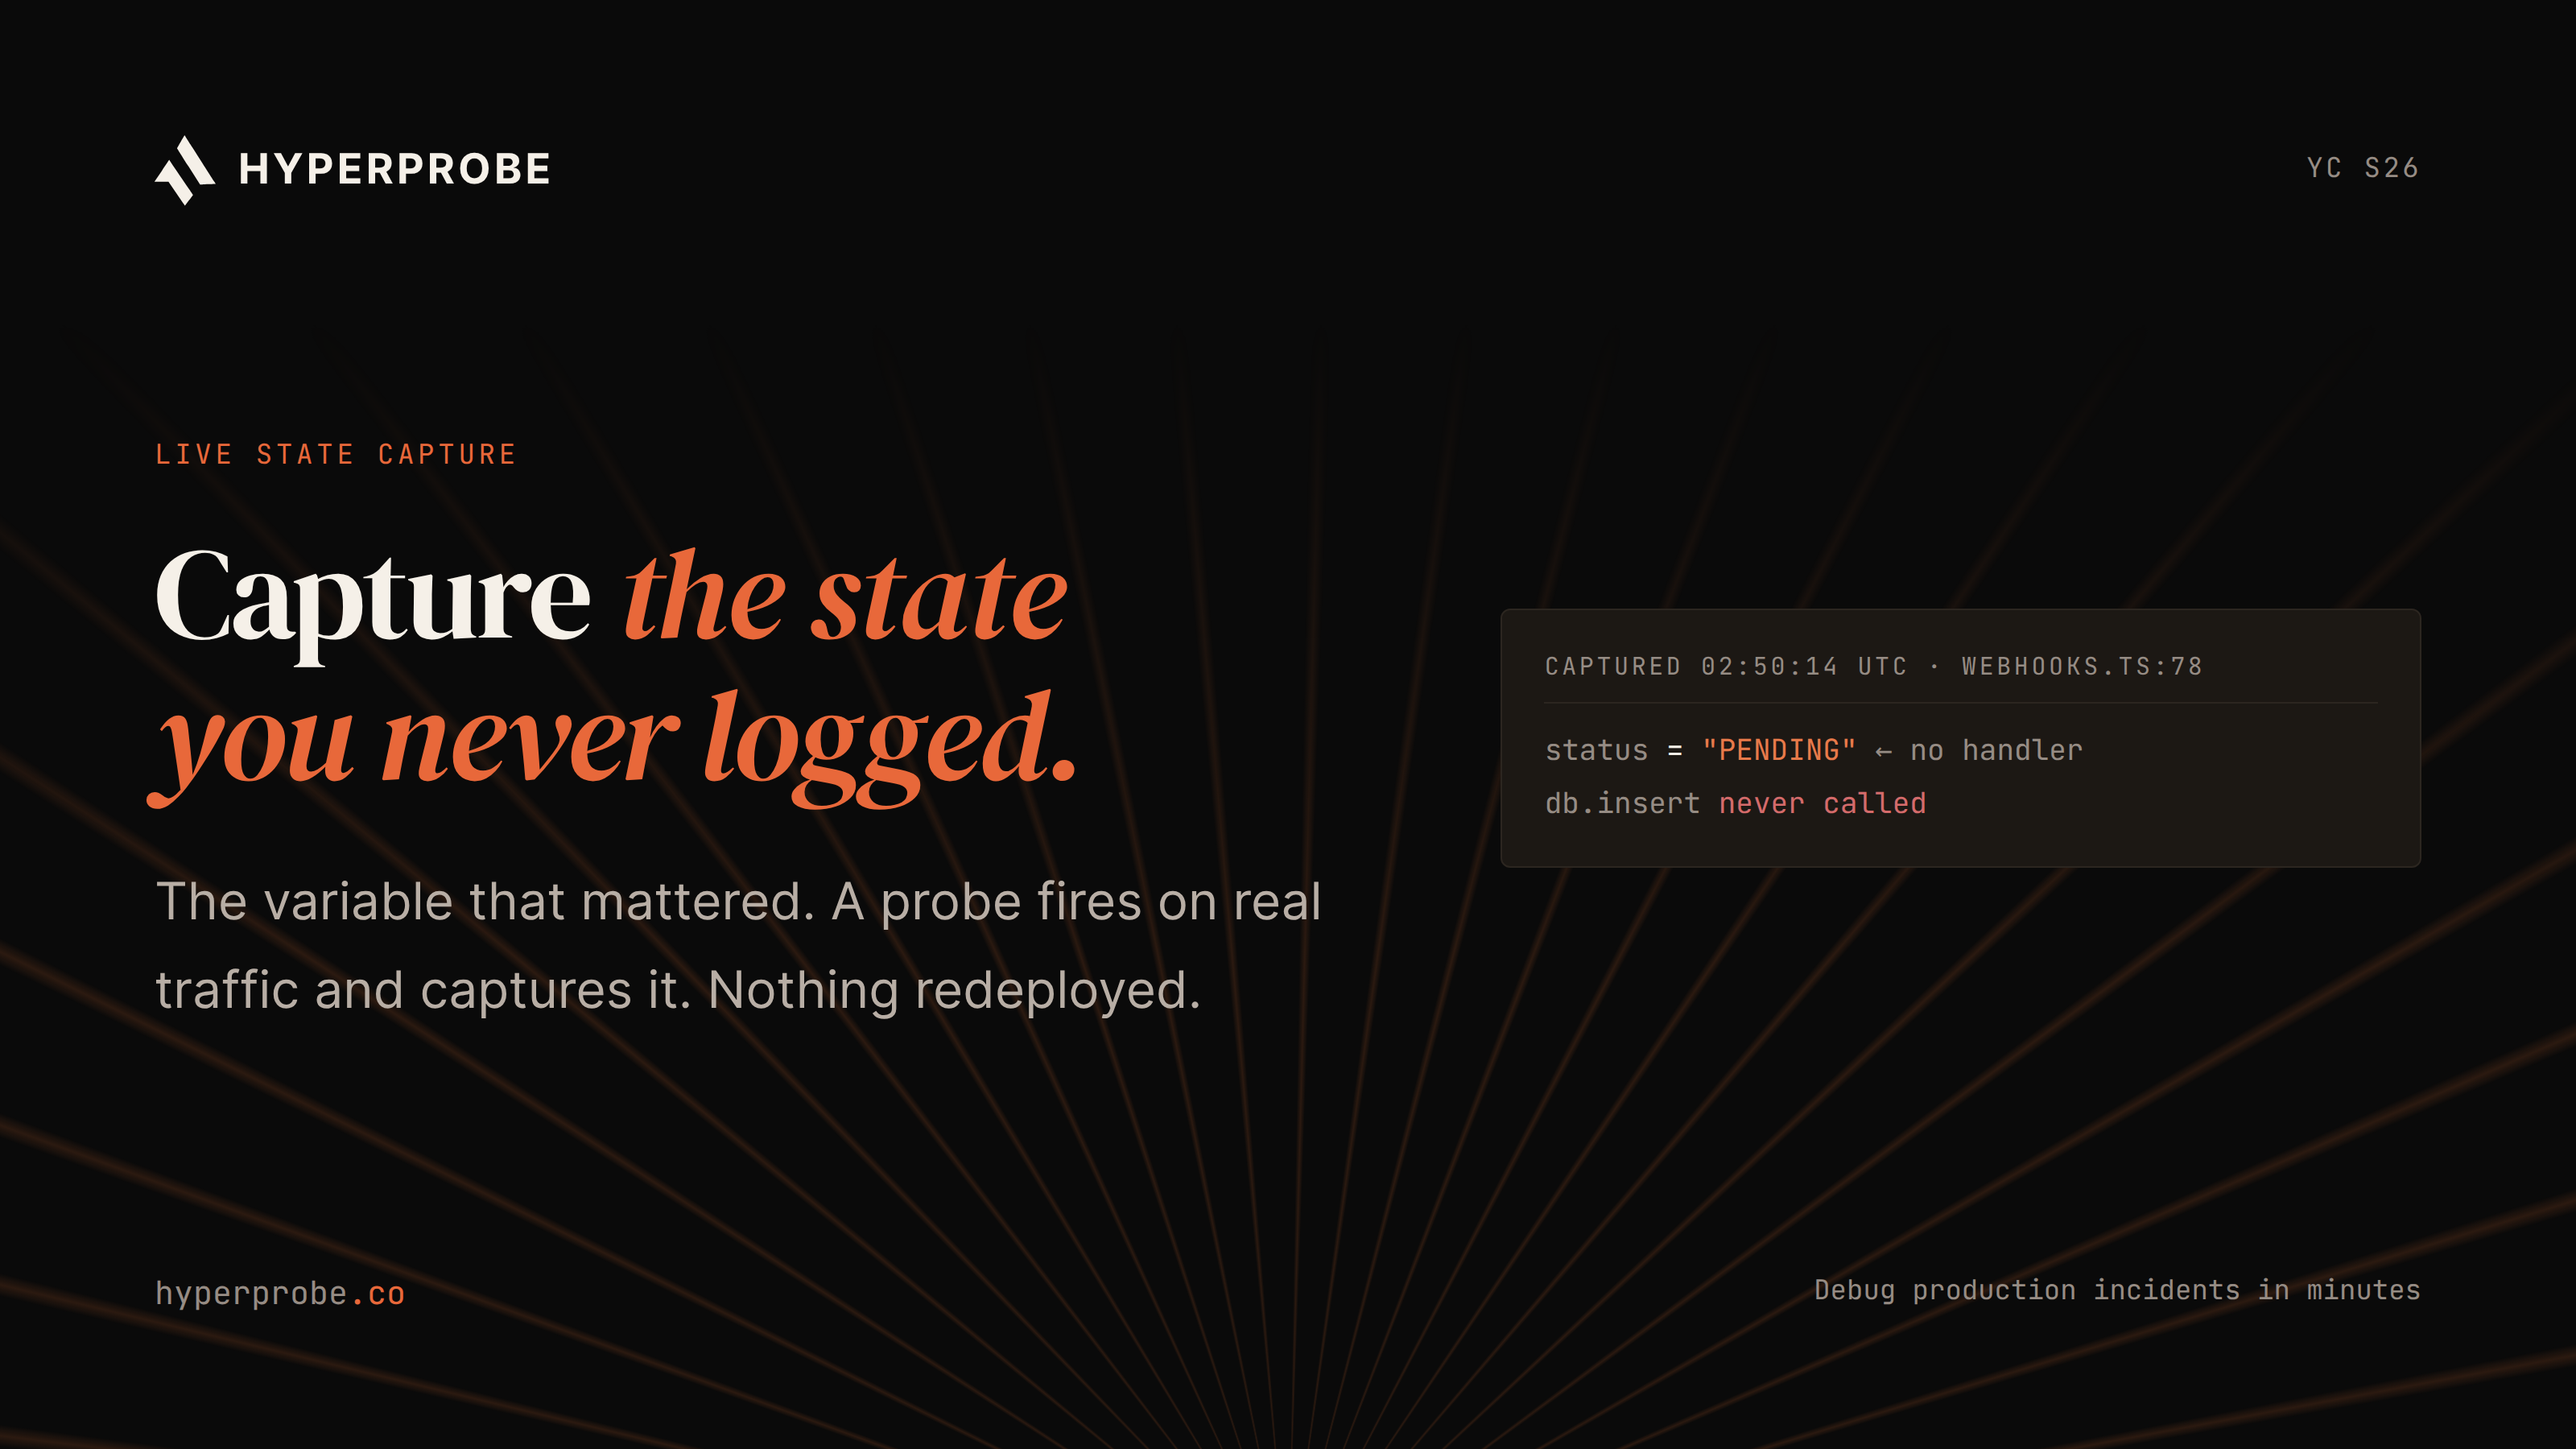
How to Capture a Variable That Was Never Logged
Learn how to capture variables in code when nothing was ever logged, from print statements and debuggers to production-safe dynamic instrumentation.
AI SRE and incident tooling
Best tools for root cause analysis of intermittent 500 errors
Compare root cause analysis tools for intermittent 500 errors, including APM, tracing, error monitoring, and AI SRE platforms. Find the right fit for your stack.